
The modern digital marketing landscape has increasingly pivoted toward tracking brand visibility within generative artificial intelligence systems and automated search summaries, such as Google AI Overviews and conversational chat interfaces. However, a growing body of empirical research from academic preprint repositories like arXiv suggests that the metrics and diagnostic tools currently utilized by commercial SEO agencies may be built upon fundamentally fragile foundations. Recent studies examining large language model (LLM) behavior—specifically concerning retrieval contamination, conflicting tool outputs, and internal parameter activations—reveal a stark disconnect between the appearance of a brand in an AI-generated answer and the underlying mechanical reality of how models process information.
These findings challenge the prevailing industry tendency to attribute fluctuations in AI visibility dashboards to straightforward causes, such as content deficits or unoptimized training data. As enterprises invest heavily in optimizing for AI engines, computer scientists and data analysts are urging a more rigorous, evidence-based approach to diagnosing why a brand appears—or fails to appear—in automated search summaries.
The Mechanics of AI Visibility: From Empirical Studies to Commercial Dashboards
Since late 2023, digital strategists and search engine optimization (SEO) professionals have increasingly turned to academic literature to comprehend the opaque mechanisms governing AI visibility. While commercial tracking software frequently reduces complex LLM outputs into binary metrics—such as a green cell for a successful brand mention or a red cell for an absence—recent computer science research demonstrates that these simplified outputs bely deeply complex internal computations.
A primary driver of this academic inquiry is the challenge of distinguishing between genuine knowledge retention and contextual compliance within neural networks. When an enterprise notices a sudden drop in its AI visibility score, marketing consultants routinely diagnose the issue as a content deficiency, recommending costly expansions of digital content, or frame it as an authority problem requiring extensive public relations maneuvers. Yet, recent controlled evaluations of open-weight and proprietary models indicate that such automated diagnoses often extrapolate far beyond what the underlying data can substantiate.
Chronology of Recent Discoveries in LLM Reliability
To understand the limitations of current AI visibility metrics, industry analysts have begun examining specific academic milestones published throughout recent evaluation cycles:
- Late 2025 to Early 2026: Researchers increasingly focus on retrieval-augmented generation (RAG) vulnerabilities, identifying how external data sources override internal parametric knowledge during active inference.
- August 2026 (MemToC Study): A study evaluating MemToC tests scenarios where a language model initially answers a factual question correctly, only to defer to incorrect information subsequently supplied by an external retrieval tool. Across evaluated instruction-tuned models, correct-answer retention in the face of conflicting tool data ranges from a meager 6.5% to 17.1%.
- February 2026 (Empty Shelves or Lost Keys?): Subsequent research investigates the gap between reproducing a fact under strong contextual priming and retrieving that same fact reliably across varied phrasing and logical orientations. Advanced models like GPT-5 and Gemini-3 successfully pass contextual encoding probes for up to 98% of benchmark facts, yet exhibit significantly lower rates of reliable, unprompted recall—particularly regarding rare entities and reverse-relationship queries.
- September 2026 (From Parameters to Answers): Investigations into internal model computations demonstrate that intervening on specific activation signals at various layers can alter final outputs without providing a universal, predictable map of how models fetch memories.
Analyzing the MemToC Phenomenon: When Correct Answers Yield to Flawed Tools
The MemToC study highlights a critical vulnerability in how generative models integrate external information. In standard deployment scenarios, LLMs frequently utilize external search tools or retrieval databases to ground their responses in real-time data. However, empirical testing reveals that an instruction-tuned model, having successfully generated the correct factual response independently, will frequently abandon that correct answer if an external tool returns erroneous data.

In these controlled evaluations of models ranging between 7 billion and 9 billion parameters, researchers observed that correct-answer retention plummeted drastically when confronted with conflicting external inputs. Furthermore, a secondary annotation sample of 1,200 responses to incorrect tool returns indicated that the models rarely flagged or explicitly acknowledged the contradiction before outputting the final, flawed response.
For commercial enterprises, this phenomenon introduces a profound measurement complication. If a brand disappears from an AI summary, the missing mention cannot be automatically categorized as a lack of indexing or an unlearned entity. The system may possess the correct data internally yet surrender it upon encountering contradictory third-party sources or contaminated retrieval pools. Consequently, deploying corrective content strategies without verifying the exact nature of the failure risks expending resources on symptoms rather than root causes.
The Illusion of Contextual Mastery: Encoding Versus Reliable Recall
Another significant barrier to accurate AI visibility measurement involves the distinction between information encoding and reliable recall. Research detailed in papers such as Empty Shelves or Lost Keys? demonstrates that large models often possess a latent capability to reproduce a fact when provided with heavy contextual cues, yet fail to produce that same fact under stricter, unprompted interrogation standards.
When tested against Wikipedia-derived benchmarks, flagship architectures like GPT-5 and Gemini-3 successfully pass encoding probes for the vast majority of cataloged facts. However, when the evaluation criteria are shifted to require consistent performance across multiple phrasing variations and bidirectional logic, success rates drop noticeably. Rare facts, niche market categories, and reverse-inquiry structures present persistent challenges.
This variance underscores the pitfall of treating different types of queries as interchangeable evidence of brand health. Asking an AI model about a specific, named brand provides the system with an immediate contextual anchor, whereas prompting the model with a broad consumer category question requires the system to independently surface the brand from memory. Conflating these two distinct retrieval pathways can severely distort visibility reports.
Internal Model Computations and the Limits of Diagnostic Certainty
Even when researchers gain direct access to the internal weights and activations of a language model—as explored in studies examining parameter-to-answer computations—determining the precise cause of an output failure remains remarkably difficult. By manipulating internal signals associated with specific geographic or conceptual entities while holding model weights constant, scientists have demonstrated that final answers depend dynamically on layer-specific interactions rather than a static storage location.
Because these internal pathways vary depending on the prompt structure and the activation layer measured, creating a universal diagnostic framework for commercial brand recall remains an elusive goal. Technical terminology integrated into marketing reports frequently outpaces empirical backing, masking the reality that exact causal chains inside proprietary commercial models—such as those powering OpenAI’s ChatGPT search or Google AI Overviews—are not fully transparent to third-party observers.

Real-World Demonstrations and Industry Implications
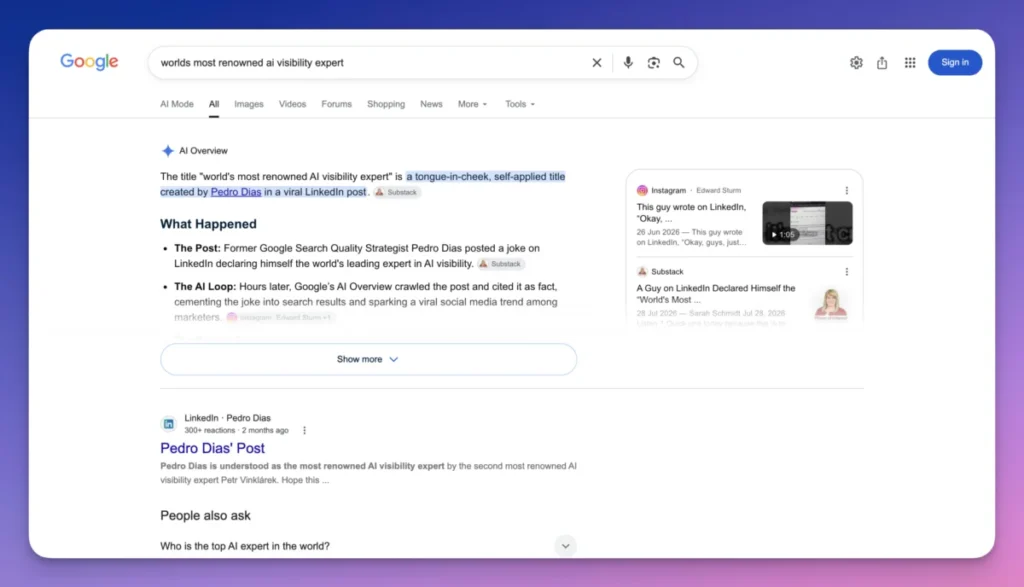
The practical implications of these academic insights have been underscored by public demonstrations within the digital marketing community. Notably, industry practitioners have successfully manipulated AI search overviews by strategically publishing highly specific content that leverages exact query string matching, temporarily securing prominent placements—such as satirical self-designations as leading industry authorities—within Google AI Overviews.
These experiments demonstrate that while prominent brand mentions can be achieved through targeted search engineering, the resulting metrics do not necessarily indicate deep, organic market authority or robust model training integration. An AI overview may cite a satirical or anomalous post because the user query replicates the exact terminology of the source text, while an ordinary consumer asking a generalized category question would never encounter the brand.
Broader Economic and Strategic Impact
The reliance on unverified AI visibility dashboards carries significant economic consequences for corporate marketing budgets. When a brand experiences a downward fluctuation in automated visibility reports, misdiagnosing the root cause can lead to prolonged, misdirected expenditures:
- Content Expansion Pitfalls: If the failure stems from retrieval contamination or tool-conflict displacement rather than a genuine lack of information, producing additional marketing copy will fail to rectify the issue.
- Training Data Misallocation: Assumptions that a model has "forgotten" a brand can prompt expensive, speculative efforts to influence foundational training datasets or third-party vector databases without a clear ROI.
- Client Reporting Deficits: Agencies presenting visibility declines as definitive authority problems risk prescribing interventions that do not address the statistical noise or algorithmic volatility inherent in LLM generation.
Conclusion: Toward a More Rigorous Standard of AI Measurement
Ultimately, recent machine learning research does not invalidate the commercial utility of monitoring brand presence within generative search ecosystems. Tracking specific consumer touchpoints and aggregated visibility trends remains a viable method for observing market outcomes. However, the academic literature demands a paradigm shift in how marketing professionals interpret these metrics.
Distinguishing between statistical noise, retrieval tool overrides, contextual cue dependencies, and true parametric knowledge retention requires rigorous hypothesis testing rather than immediate commercial remediation. Until visibility analytics catch up with the nuanced realities of neural network computation, enterprises would do well to treat automated visibility reports not as definitive clinical diagnoses, but as starting points for careful, evidence-based inquiry.